InfoLab Blog

New Paper: Federated Learning Under Data Heterogeneity

We are excited to share our latest paper accepted at IMCOM 2025: Towards Robust Federated Learning: Investigating Poisoning Attacks Under Clients Data Heterogeneity.

Abdenour Soubih January 10, 2025 1 min read

We are excited to share our latest paper accepted at IMCOM 2025: Towards Robust Federated Learning: Investigating Poisoning Attacks Under Clients Data Heterogeneity.

Federated learning enables collaborative model training across distributed clients without sharing raw data — but it remains vulnerable to poisoning attacks, especially when client data distributions are heterogeneous.

Our work systematically evaluates state-of-the-art poisoning attack strategies under realistic non-IID data settings. We analyze how data heterogeneity affects attack success rates and propose defenses tailored to this challenging scenario.

Key contributions:

  • Comprehensive evaluation of poisoning attacks under varying degrees of data heterogeneity
  • Analysis of why standard defenses (FedAvg + median/trimmed-mean aggregation) fail in non-IID settings
  • Lightweight mitigation strategy that degrades attack success without sacrificing model accuracy

The full paper is available on our publications page.

More from the Blog

Sep 03, 2026 3 min read
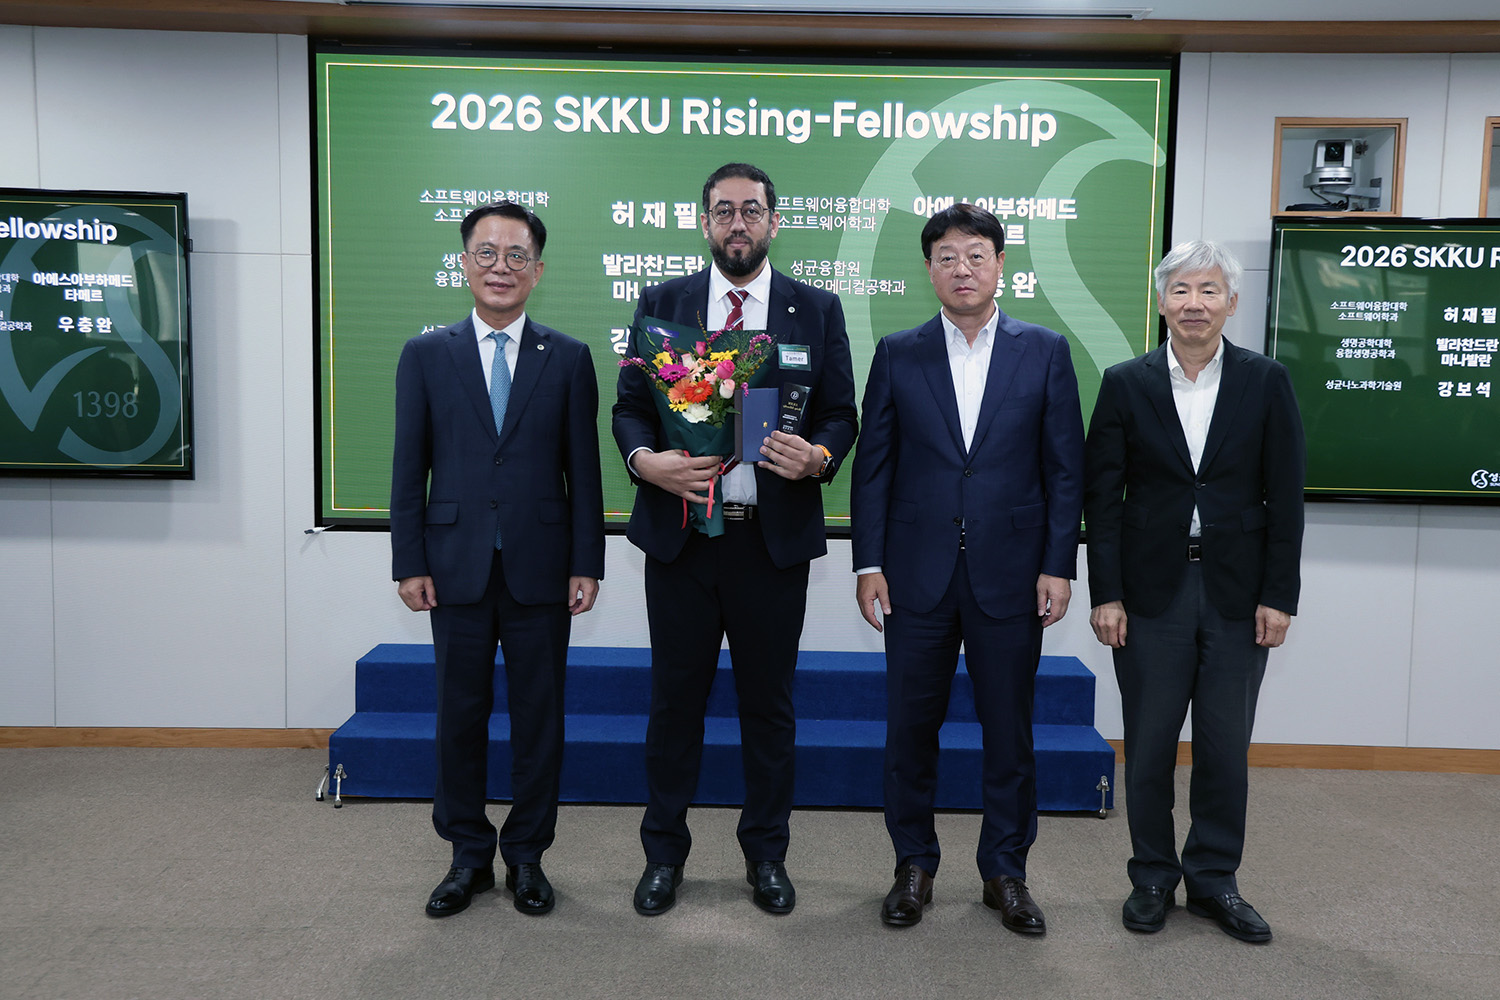
Prof. Tamer Abuhmed Selected for the 2026 SKKU Rising-Fellowship

> — **Prof. Tamer Abuhmed**The fellowship further reflects SKKU's commitment to fostering internationally competitive research and supporting faculty members with the potential to lead their respective research fields at the global level."> Prof. Tamer Abuhmed, Associate Professor in the Department of Computer Science and Engineering and Director of the Information Research Laboratory (InfoLab) at Sungkyunkwan Univ...

May 17, 2026 9 min read
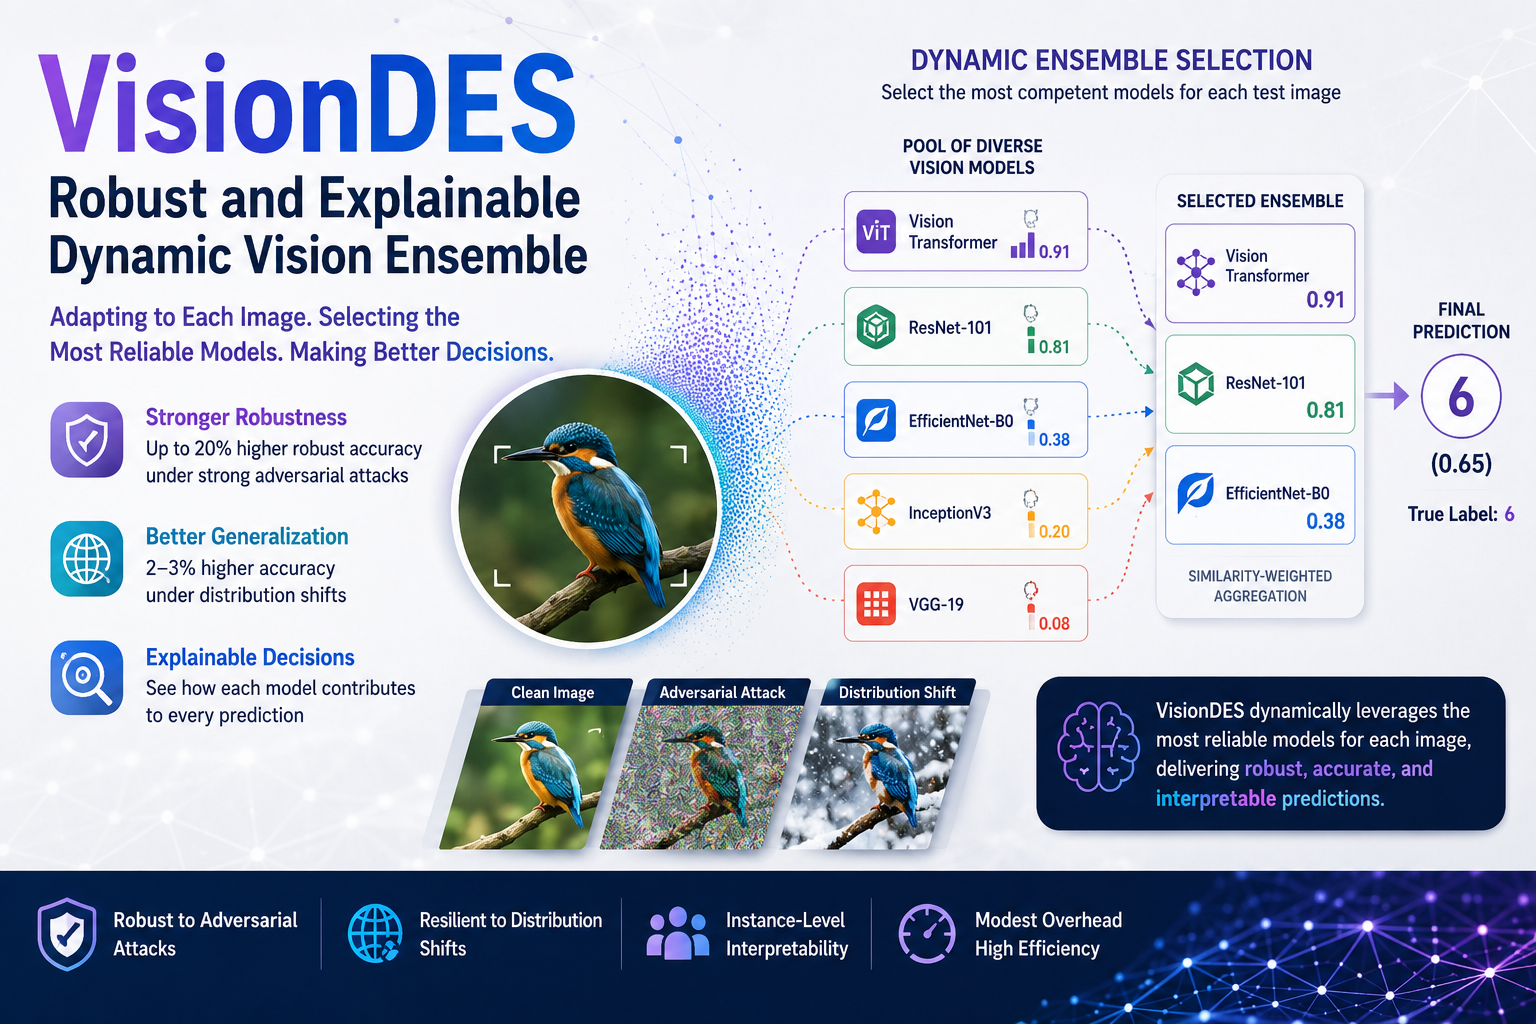
VisionDES: Robust and Explainable Dynamic Vision Ensemble

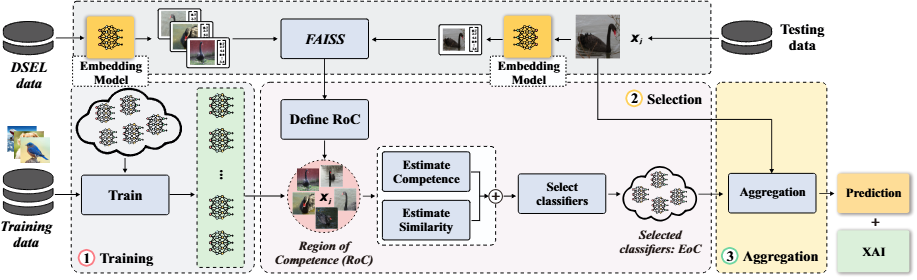
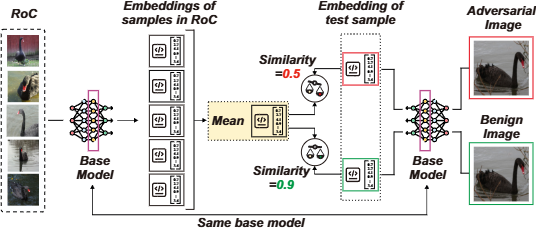
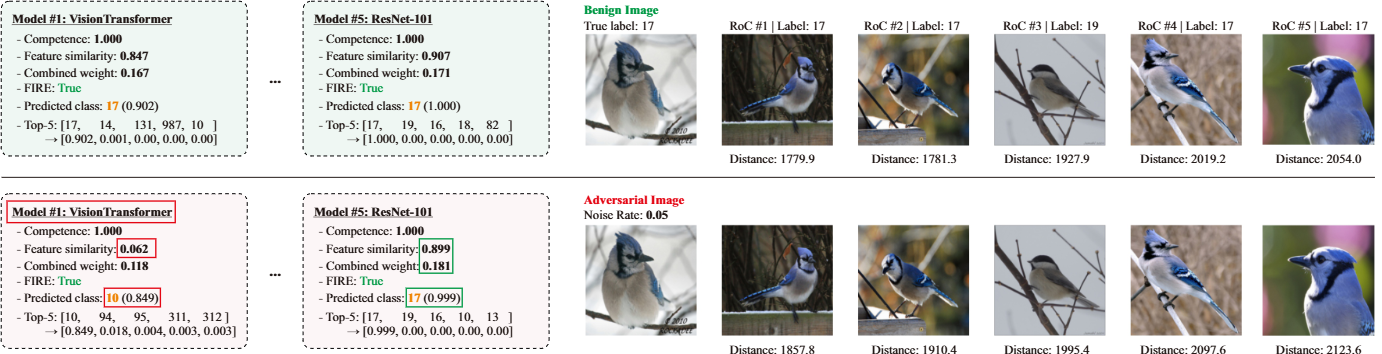
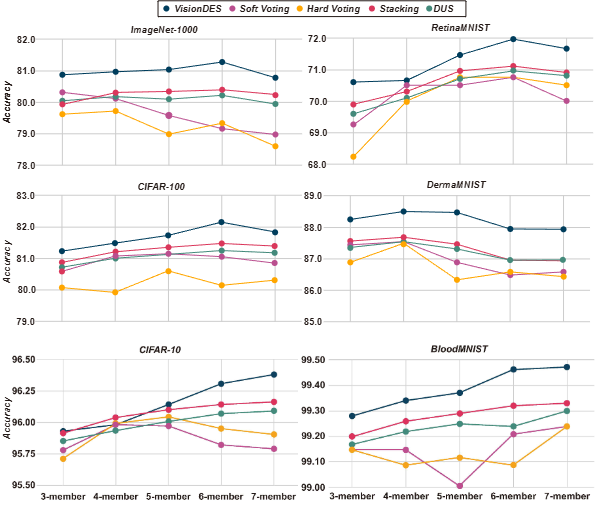
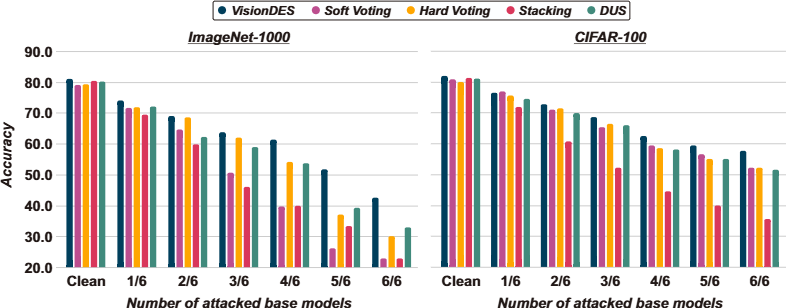
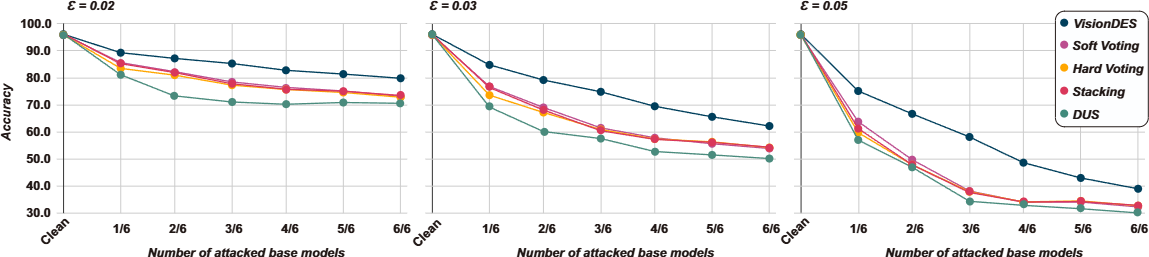
**Key innovation:** VisionDES uses DINO-based ViT embeddings and FAISS approximate nearest-neighbor search to construct a local Region of Competence in embedding space for each test sample — then dynamically selects and weights classifiers based on both their local accuracy and feature-space consistency.### Three Stages**Stage 1 — Training**Diverse vision models (ViT, ResNet, EfficientNet, VGG, etc.) are trained. DINO embeddings of a validation set (DSEL) are indexed in a FAISS store for fast retrieval.**Stage 2 — Selection**For each test image, its DINO embedding is computed and *k*=7 nearest neighbors are retrieved, defining the RoC. Classifiers are scored by their accuracy within that region using one of three selection rules:- **KNORA-U**: includes any classifier that correctly labels at least one RoC sample, weighted by competence score.- **KNORA-E**: the stricter rule — only classifiers that correctly label *all* RoC samples are selected.- **FIRE**: handles indecision regions near class boundaries by requiring correct predictions from each class present in the RoC.**Stage 3 — Aggregation**Selected classifiers are combined via similarity-weighted voting. Models whose internal representations diverge from the RoC mean are automatically down-weighted.![Figure 2: VisionDES framework](/images/blogs/desvision/Figure2.png)**Figure 2.** The VisionDES framework. At test time, the input image's DINO embedding is used to retrieve a Region of Competence from the DSEL store. Competence and similarity scores are jointly computed and fused to produce the final weighted prediction.---## Similarity-Weighted CompetenceThe most distinctive technical contribution of VisionDES is the **similarity-weighted competence mechanism**. Classical DES methods assign weights based solely on a classifier's accuracy within the RoC. VisionDES adds a second signal: *feature-space consistency*.For each classifier `c_i`, VisionDES computes the cosine similarity between the mean embedding of RoC samples (as seen through `c_i`'s penultimate layer) and the embedding of the test image itself. When a model has been adversarially perturbed, its internal representations become misaligned with those of clean neighboring samples — its similarity score drops, and so does its contribution.The competence and similarity scores are fused via a convex combination:```textw_i(t) = α_t · comp_i(t) + (1 − α_t) · s_i(t)```The mixing coefficient `α` is estimated *adaptively* per test sample, based on the relative variability of each signal across the ensemble. This lets similarity dominate when it provides a strong discriminative signal, while falling back to competence when similarity scores are homogeneous.![Figure 3: Similarity-weighted aggregation](/images/blogs/desvision/Figure3.png)**Figure 3.** Similarity-weighted aggregation. For a benign image, a model's internal representation closely matches the RoC mean — similarity ≈ 0.9. For an adversarially perturbed input, the same model's representation drifts away — similarity drops to ≈ 0.5 — automatically reducing its weight in the ensemble decision.---## Instance-Level InterpretabilityBeyond robustness, VisionDES is **inherently interpretable**. Because classifier selection is explicit and per-sample, the framework reports — for any given prediction — exactly:- Which models were selected- Each model's competence score and feature similarity score- Each model's assigned weight- Each model's top-5 class predictionsThe Region of Competence is also visualized: the nearest validation samples are shown alongside their L2 distances to the test image, giving a concrete picture of the neighborhood in which the decision was made.![Figure 4: Interpretability under benign and adversarial conditions](/images/blogs/desvision/Figure4.png)**Figure 4.** Interpretability output for a test image under benign conditions (top) and under a PGD adversarial attack on the ViT model (bottom). Under attack, the ViT's feature similarity collapses from 0.847 to 0.062 — its combined weight is automatically reduced. Unattacked models maintain stable similarity and correct predictions. The RoC structure is largely preserved thanks to DINO's robustness.---## Experimental ResultsVisionDES is evaluated across three settings — clean conditions, adversarial attacks, and distribution shift — on ImageNet, CIFAR-10, CIFAR-100, and three MedMNIST datasets (RetinaMNIST, BloodMNIST, DermaMNIST).### Clean PerformanceUnder standard conditions, VisionDES consistently matches or outperforms soft voting, hard voting, stacking, and DUS across all benchmarks. Notably, while soft and hard voting *degrade* when weaker models are added to the pool, VisionDES continues to improve — rising to **81.25%** on ImageNet with six models, up from 80.95% with three. VisionDES can identify and down-weight weaker classifiers per-sample, rather than blending them in unconditionally.![Figure 5: Clean performance comparison](/images/blogs/desvision/Figure5.png)**Figure 5.** Accuracy as a function of ensemble pool size under clean conditions on ImageNet-1000, CIFAR-100, RetinaMNIST, and DermaMNIST. VisionDES consistently outperforms static methods and DUS, and uniquely continues to improve as weaker models are added.### Adversarial RobustnessWe stress-test VisionDES with ensemble adversarial attacks, increasing the fraction of attacked base models from 1/6 to 6/6. When **83.3% of models are under PGD attack** on ImageNet:| Method | Accuracy ||---|---|| **VisionDES** | **51.72%** || DUS | 39.45% || Hard Voting | 37.08% || Stacking | 33.53% || Soft Voting | 26.24% |VisionDES also holds up across all four attack strategies. Under the **C&W attack** with all models targeted, VisionDES achieves **81.55% accuracy** vs. 59.0% (soft), 61.9% (hard), 61.15% (stacking), and 64.8% (DUS) — an advantage exceeding 16 percentage points.Attack order also matters: targeting stronger models first produces more transferable adversarial examples, strongly impacting static ensembles. VisionDES remains stable across both orderings, confirming that dynamic selection and similarity-weighted aggregation mitigate transferability effects.![Figure 6: Robustness under ensemble PGD attacks](/images/blogs/desvision/Figure6.png)**Figure 6.** Ensemble robustness under PGD attack (ε=0.05 for ImageNet, ε=8/255 for CIFAR-100), with the number of attacked base models increasing from 1/6 to 6/6. VisionDES maintains a significantly higher accuracy floor as more models are compromised.### Increasing Perturbation BudgetAs the adversarial budget grows, the performance gap widens. At **ε=0.031**, VisionDES maintains accuracy gains exceeding 13% over static ensembles. At **ε=0.05** with half the pool attacked, VisionDES achieves over **20% higher accuracy** than both static methods and DUS.![Figure 8: Performance under various PGD epsilon values](/images/blogs/desvision/Figure8.png)**Figure 8.** Ensemble accuracy on CIFAR-10 under PGD with ε ∈ {0.02, 0.031 (8/255), 0.05}, attacking models strongest-to-weakest. The advantage of VisionDES widens with both higher perturbation budget and more models attacked.### Distribution ShiftUnder natural distribution shift (CIFAR-10 → CIFAR-10.1), the accuracy drop for VisionDES with seven models is **5.28%**, compared to 6.36% (soft), 6.57% (hard), 6.77% (stacking), and 7.05% (DUS). Under synthetic Gaussian noise (σ=0.04), VisionDES sees an 11.1–11.9% drop versus 13–14% for static ensembles — consistently the smallest degradation across pool sizes.---## Ablation Highlights**Why DINO?**DINO-ViT achieves the highest cosine similarity between clean and perturbed embeddings (≈0.990–0.996), far outpacing ResNet-50 (0.894) and CLIP-ViT (0.969–0.979) under CNN-generated noise. DINO's perturbation robustness keeps the Region of Competence stable even when base classifiers are under attack.**Neighborhood size.**`k=7` provides a stable balance between local sensitivity (`k=5`) and neighborhood dilution (`k=10`). Label agreement is consistent across K-NN, HNSW, and FAISS backends, confirming that embedding quality — not retrieval algorithm — is the dominant factor.**Inference overhead.**VisionDES requires ~71 ms per sample on ImageNet vs. ~28–36 ms for static methods. This is substantially reduced by precomputing base model predictions on the DSEL set. FAISS IndexIVFPQ can compress the embedding index to just **1.67 MB** for memory-constrained deployment with no impact on inference time.**Larger pools.**The benefits scale with ensemble size. An 8-member ensemble maintains accuracy above 80% across all attack ratios on CIFAR-10, outperforming both static methods and smaller VisionDES pools.---## ConclusionVisionDES demonstrates that the question for ensemble learning should not be *"how many models?"* but *"which models, for this image?"*. By introducing Dynamic Ensemble Selection to computer vision — grounded in robust DINO embeddings, FAISS-powered neighborhood search, and similarity-weighted competence estimation — VisionDES consistently outperforms static ensembles and uncertainty-based dynamic methods under clean, adversarial, and distribution-shifted conditions.Beyond raw performance, the framework's instance-level interpretability makes its decisions auditable and trustworthy, which is essential for safety-critical deployment. We see natural extensions toward multimodal ensembles, federated dynamic selection, and robust medical imaging systems.We look forward to presenting this work at **ACM SIGKDD 2026 in Jeju Island, South Korea**.---## Citation```bibtex@inproceedings{visiondes2026, title = {VisionDES: Robust and Explainable Dynamic Vision Ensemble}, author = {Firuz Juraev, Mohammed Abuhamad, Shaker El-Sappagh, Simon S. Woo, Tamer Abuhmed}, booktitle = {Proceedings of the ACM SIGKDD International Conference on Knowledge Discovery and Data Mining (KDD)}, year = {2026}}```"> > **Accepted at ACM SIGKDD 2026 · Jeju Island, South Korea** > Code: [github.com/InfoLab-SKKU/VisionDES](https://github.com/InfoLab-SKKU/VisionDES) --- ## Overview Dynamic En...
May 12, 2026 8 min read
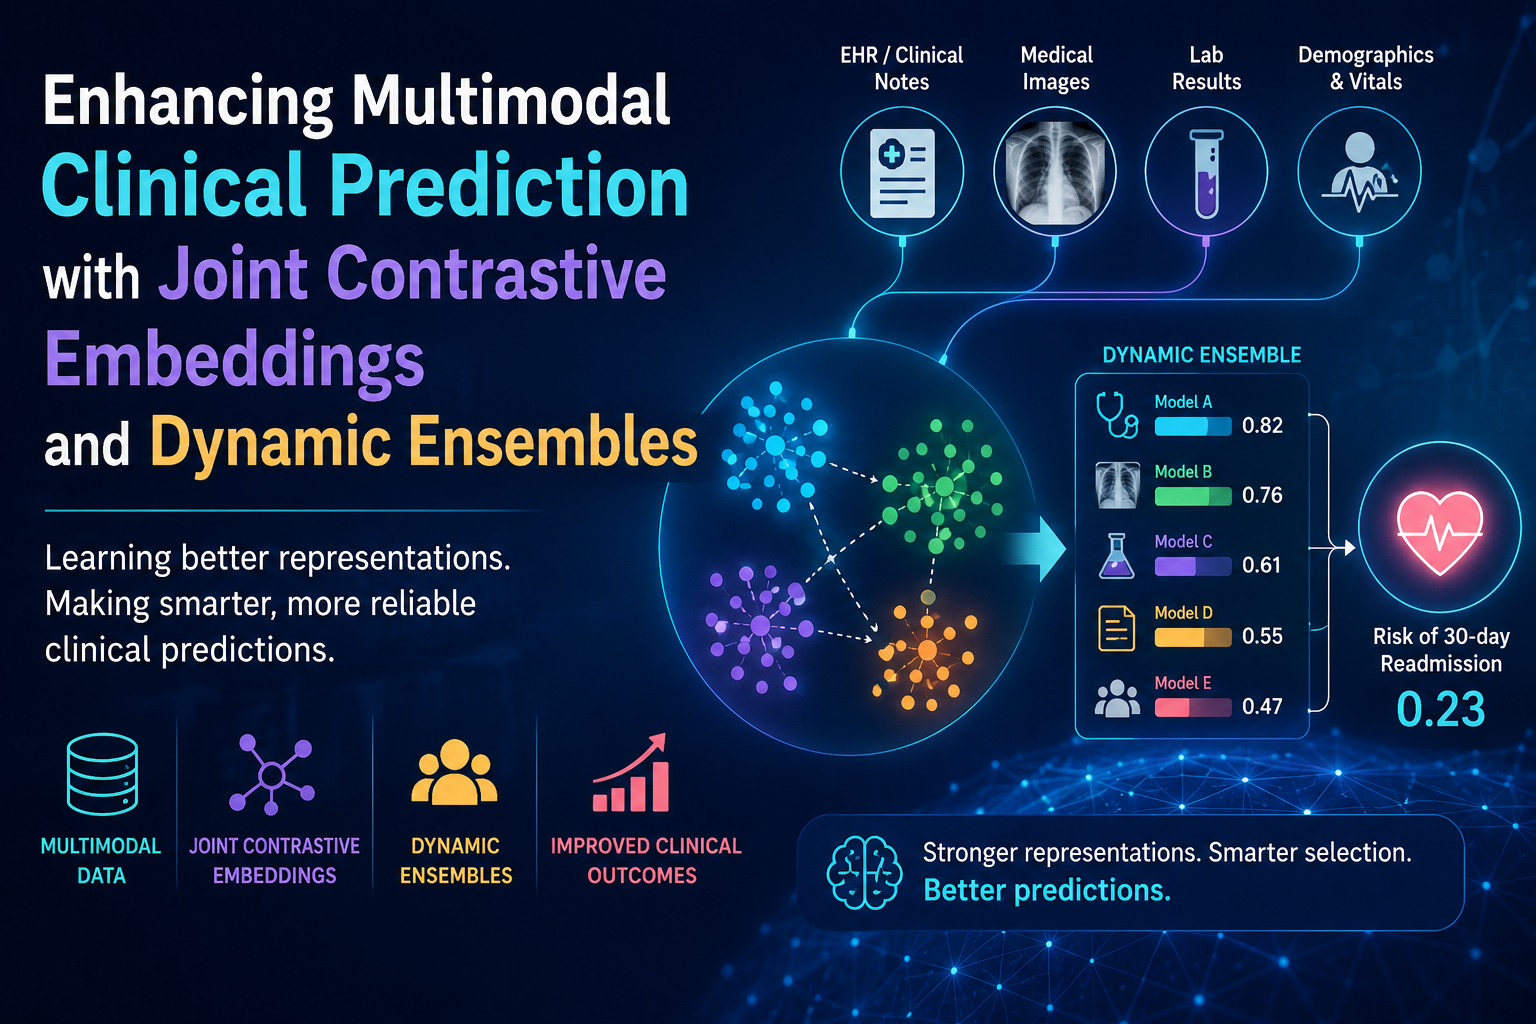
MM-DES: Enhancing Multimodal Clinical Prediction with Joint Contrastive Embeddings and Dynamic Ensembles

**Missing modality handling:** When a modality is absent, MM-DES zeros out its weight and constructs the RoC from available modalities only — no imputation, no retraining. This makes the framework naturally robust to partial and complete modality absence.---## Datasets and Base Classifiers### PAD-UFES-20 — Skin Lesion ClassificationA publicly available dataset of 2,298 smartphone-acquired skin lesion images paired with patient metadata across six lesion categories (BCC, MEL, SCC, ACK, NEV, SEK), with all cancer cases biopsy-confirmed.**Classifier pool (10 models):**- **Image:** ResNet-18, ResNet-34, EfficientNet-B0, MobileNet-V2, RegNet- **Tabular:** Random Forest, CatBoost, XGBoost, MLP, SVCBest single models: CatBoost (82.17% acc, 95.86% AUROC) · ResNet-18 (76.96% acc, 92.60% AUROC)### MIMIC-IV — Sepsis PredictionA balanced cohort of 8,156 patients (4,078 sepsis / 4,078 non-sepsis) from the MIMIC-IV clinical database, combining three modalities: radiology report text (INDICATION section), structured vital-sign summaries, and chest X-ray images.**Classifier pool (11 models):**- **Text:** ClinicalBERT, PubMedBERT, BioBERT- **Tabular:** CatBoost, XGBoost, Random Forest, MLP, SVC- **Image:** ViT-Tiny, ResNet-18, MobileNet-V2---## Results### PAD-UFES-20MM-DES achieves the best results across all four metrics:| Model | Modality | Accuracy | F1 | Bal Acc | AUROC ||---|---|---|---|---|---|| **MM-DES (Ours)** | **MM** | **85.22%** | **79.73%** | **76.20%** | **96.99%** || AutoPrognosis-M | MM | 83.26% | 77.65% | 74.51% | 96.70% || Static Ensemble (Soft) | Tabular | 82.39% | 71.82% | 66.91% | 96.07% || Best Tab (CatBoost) | Tabular | 82.17% | 74.40% | 70.16% | 95.86% || Best Img (ResNet-18) | Image | 76.96% | 70.42% | 66.13% | 92.60% |The gain in **balanced accuracy** (+1.69% over AutoPrognosis-M) is particularly meaningful: dynamic, locally-estimated classifier selection helps overcome class imbalance that static ensembles struggle with.### MIMIC-IV Sepsis Prediction| Model | Modality | Accuracy | F1 | Bal Acc | AUROC ||---|---|---|---|---|---|| **MM-DES (Ours)** | **MM-LTI** | **77.17%** | **76.99%** | **77.18%** | **86.14%** || **MM-DES (Ours)** | **MM-LT** | **75.98%** | **75.78%** | **75.98%** | **83.86%** || AutoPrognosis-M | MM-LTI | 74.34% | 74.11% | 74.32% | 82.01% || AutoPrognosis-M | MM-LT | 73.68% | 73.40% | 73.68% | 80.42% || Static Ensemble (Soft) | Text | 72.84% | 73.92% | 72.84% | 80.13% || Best Tab (CatBoost) | Tabular | 71.65% | 71.56% | 71.65% | 77.72% |MM-LT = language + tabular; MM-LTI = language + tabular + image.---## Robustness to Missing ModalitiesA defining challenge in clinical deployment is modality absence. MM-DES handles this gracefully — by constructing the RoC from whatever modalities are available.### PAD-UFES-20| Setting | Missing | Accuracy | F1 | Bal Acc | AUROC ||---|---|---|---|---|---|| Full | None | 85.22% | 79.73% | 76.20% | 96.99% || Image only | Tabular (100%) | 77.61% | 70.40% | 67.81% | 93.20% || Tabular only | Image (100%) | 82.83% | 72.65% | 67.71% | 96.20% || Partial | Tabular (20%) | 82.10% | 76.20% | 72.90% | 95.40% || Partial | Image (20%) | 84.10% | 78.10% | 74.80% | 96.50% |Under a realistic 20% partial-missing rate, performance remains within 1–3% of the fully-observed baseline. The system does not over-rely on any single modality.![Figure 2: Missing modality results table](/images/blogs/mmdes/Figure2.png)---## Instance-Level InterpretabilityMM-DES provides multi-level interpretability for every prediction:**Model contributions:** for each classifier in the pool, MM-DES reports the prediction, competence score `κ`, and assigned weight `w` — revealing which models the ensemble relied on and why.**Modality-level insights:** the applied modality weights are reported explicitly, showing whether the final decision was driven by imaging, tabular variables, or clinical text.**Feature-level explanations:**- **Image models** → Grad-CAM highlights salient lesion regions- **Tabular models** → SHAP quantifies feature contributions (e.g., smoking history, age, vital signs)- **Language models** → CAPTUM attributes importance to specific tokens in clinical notes![Figure 3: PAD-UFES-20 interpretability](/images/blogs/mmdes/Figure3.png)**Figure 3.** Interpretability output for a PAD-UFES-20 test sample. Despite image models initially receiving higher weights, competence analysis reveals that tabular models perform better locally and correctly drive the prediction. SHAP shows smoking history and age are the most important features; Grad-CAM highlights the lesion region.---## Ablation Highlights**Neighborhood size (k):** Performance peaks at `k=10` and plateaus. Smaller neighborhoods (k=5) introduce instability; larger ones (k=15) dilute locality. Default: `k=10`.| k | Accuracy | F1 | Bal Acc | AUROC ||---|---|---|---|---|| 5 | 84.78% | 79.30% | 75.52% | 96.43% || 7 | 85.00% | 79.24% | 75.55% | 96.64% || **10** | **85.22%** | **79.73%** | **76.20%** | **96.99%** || 12 | 85.03% | 79.63% | 76.11% | 96.94% || 15 | 85.03% | 79.63% | 76.11% | 96.94% |**Modality weights:** Emphasizing tabular slightly more (0.4 image, 0.6 tabular) yields the best results for PAD-UFES-20, reflecting the higher discriminative power of structured clinical variables.| Img | Tab | Accuracy | AUROC ||---|---|---|---|| 0.2 | 0.8 | 84.35% | 94.51% || 0.3 | 0.7 | 84.78% | 95.02% || **0.4** | **0.6** | **85.22%** | **96.99%** || 0.5 | 0.5 | 84.13% | 95.91% || 0.6 | 0.4 | 84.04% | 94.98% |**Search backend:** FAISS (67 ms, 1.8 MB) outperforms both HNSW (70 ms, 2.1 MB) and brute-force K-NN (970 ms, 1.8 MB) on latency — the clear choice for clinical deployment.---## ConclusionMM-DES demonstrates that Dynamic Ensemble Selection, previously confined to unimodal tabular settings, can be successfully extended to multimodal clinical prediction. By grounding the Region of Competence in contrastive multimodal embeddings, MM-DES achieves sample-adaptive model selection that naturally handles missing modalities, improves over static multimodal ensembles, and remains interpretable at the instance level.The results across PAD-UFES-20 and MIMIC-IV show consistent improvements over AutoPrognosis-M and unimodal baselines, with the largest gains in challenging missing-modality and class-imbalanced scenarios — precisely the conditions most common in real clinical deployment.**Future directions:** adaptive per-sample modality weighting, uncertainty-aware DES parameter selection, richer modality-contribution analyses, and extension to larger clinical datasets.---## Citation```bibtex@inproceedings{mmdes2026, title = {MM-DES: Enhancing Multimodal Clinical Prediction with Joint Contrastive Embeddings and Dynamic Ensembles}, author = {Juraev, Firuz and Soubih, Abdenour and Abuhmed, Tamer}, booktitle = {Proceedings of the International Conference on Pattern Recognition (ICPR)}, year = {2026}}```---*This work was supported by the National Research Foundation of Korea (NRF) grant RS-2021-NR058558 and IITP-ICT Creative Consilience Program (IITP-2026-RS-2020-II201821).*"> > **Accepted at ICPR 2026** > **Authors:** Firuz Juraev, Abdenour Soubih, Tamer Abuhmed · Sungkyunkwan University > **Code:** [github.com/InfoLab-SKKU/mm-des](https://github.com...

View All Posts